diff --git a/sites/en/docs/Edge/NVIDIA_Jetson/Application/Generative_AI/Accelerate_LLM_Inference_with_MTP_on_Jetson.md b/sites/en/docs/Edge/NVIDIA_Jetson/Application/Generative_AI/Accelerate_LLM_Inference_with_MTP_on_Jetson.md new file mode 100644 index 00000000000000..72f19fc4e2d308 --- /dev/null +++ b/sites/en/docs/Edge/NVIDIA_Jetson/Application/Generative_AI/Accelerate_LLM_Inference_with_MTP_on_Jetson.md @@ -0,0 +1,218 @@ +--- +title: Speed Up llama.cpp on NVIDIA Jetson AGX Orin with MTP +description: Enable Multi-Token Prediction in llama.cpp on NVIDIA Jetson AGX Orin. Follow Qwen3.5-4B setup steps and compare MTP ON/OFF benchmark results. +keywords: + - NVIDIA Jetson + - Jetson AGX Orin + - MTP + - Multi-Token Prediction + - speculative decoding + - llama.cpp + - Qwen3.5 + - edge AI +slug: /jetson/accelerate_llm_inference_mtp +draft: false +image: https://files.seeedstudio.com/wiki/Jetson/Application/jetson-mtp-cover-en.png +last_update: + date: 10/23/2026 + author: zibo +createdAt: '2026-10-23' +updatedAt: '2026-10-23' +url: https://wiki.seeedstudio.com/jetson/accelerate_llm_inference_mtp/ +--- + +# Speed Up llama.cpp on NVIDIA Jetson AGX Orin with MTP +
+ NVIDIA Jetson illustration with Qwen3.5-4B, llama.cpp, and an MTP token-flow graphic. +
+ +
+ + Get One Now 🖱️ + +
+ +## Introduction + +This wiki explains how Multi-Token Prediction (MTP) works and how to enable it in **llama.cpp on NVIDIA Jetson AGX Orin with Qwen3.5-4B**. Follow the setup and compare MTP ON/OFF performance using a local crowd-monitoring demo. + +First, look at the actual test results. We had the LLM generate a Python script for computing the Fibonacci sequence, and compared the generation speed with and without the MTP model enabled. + +
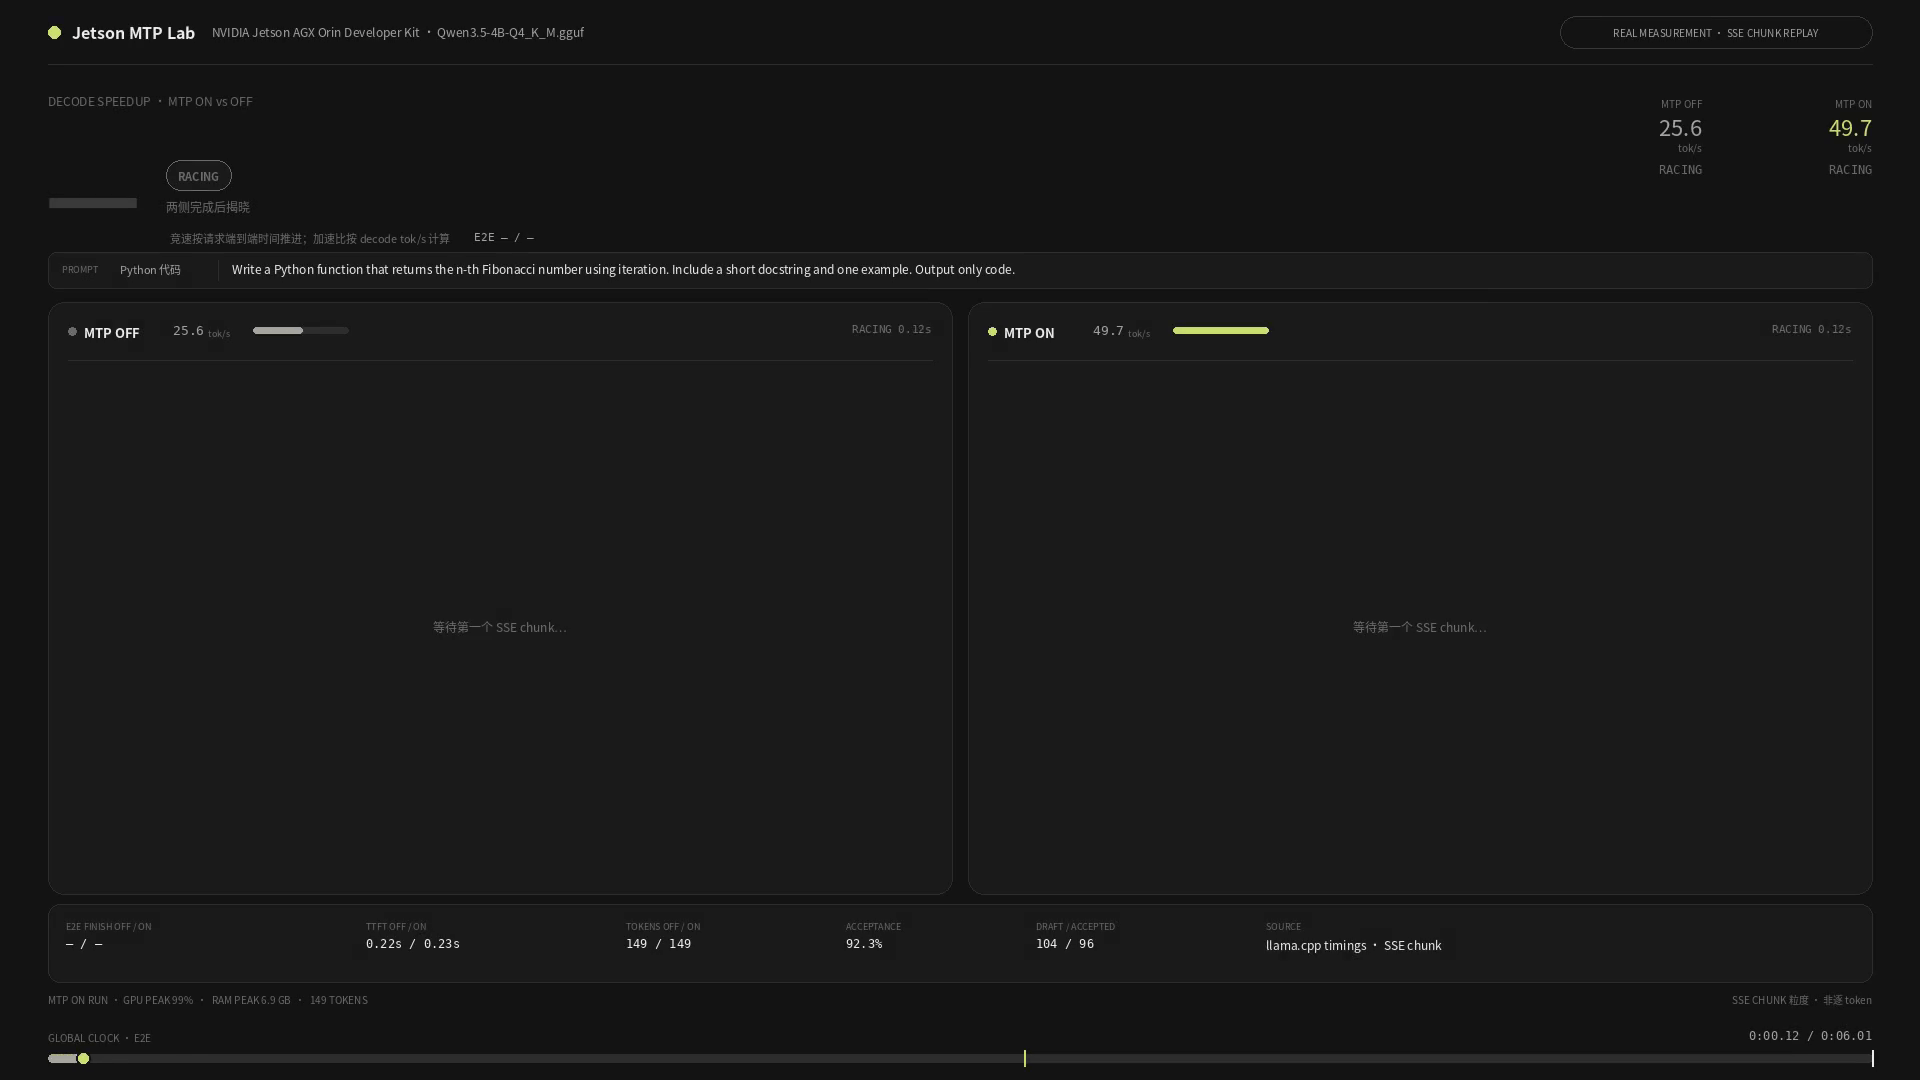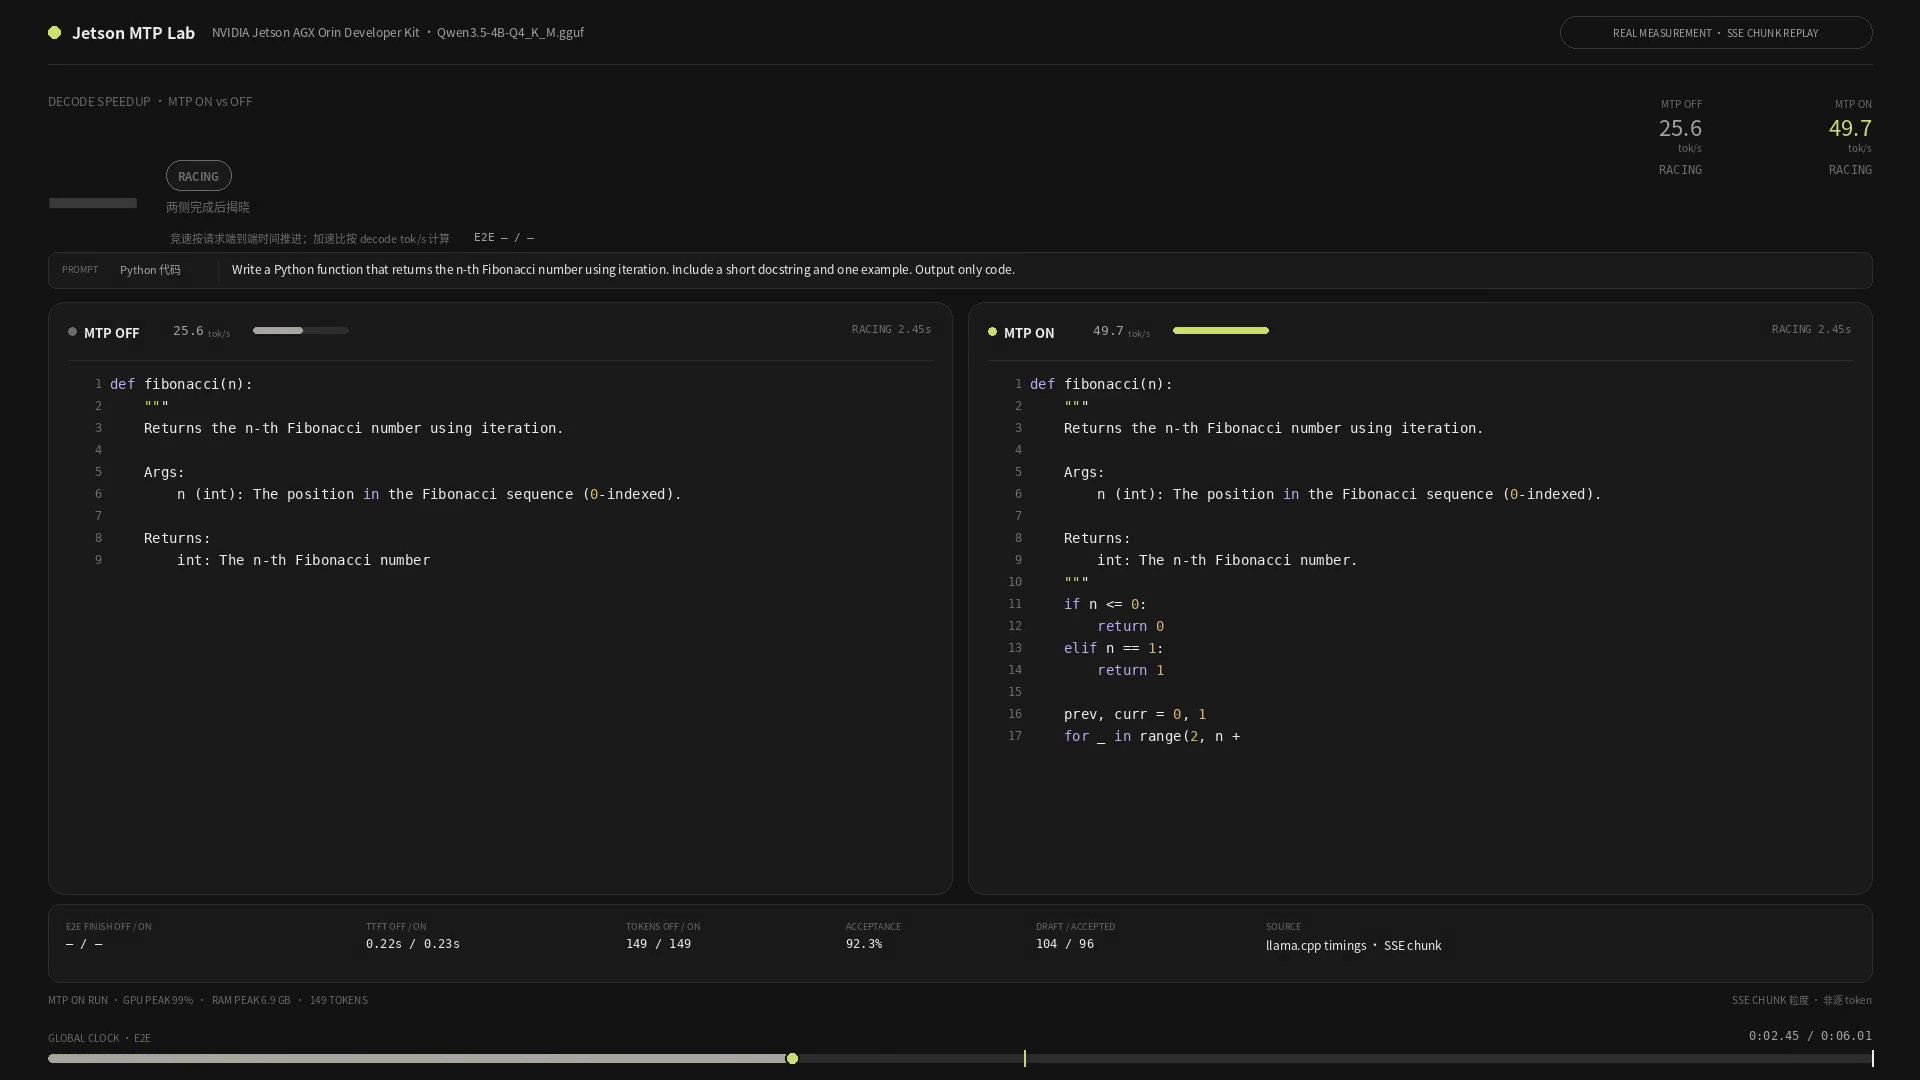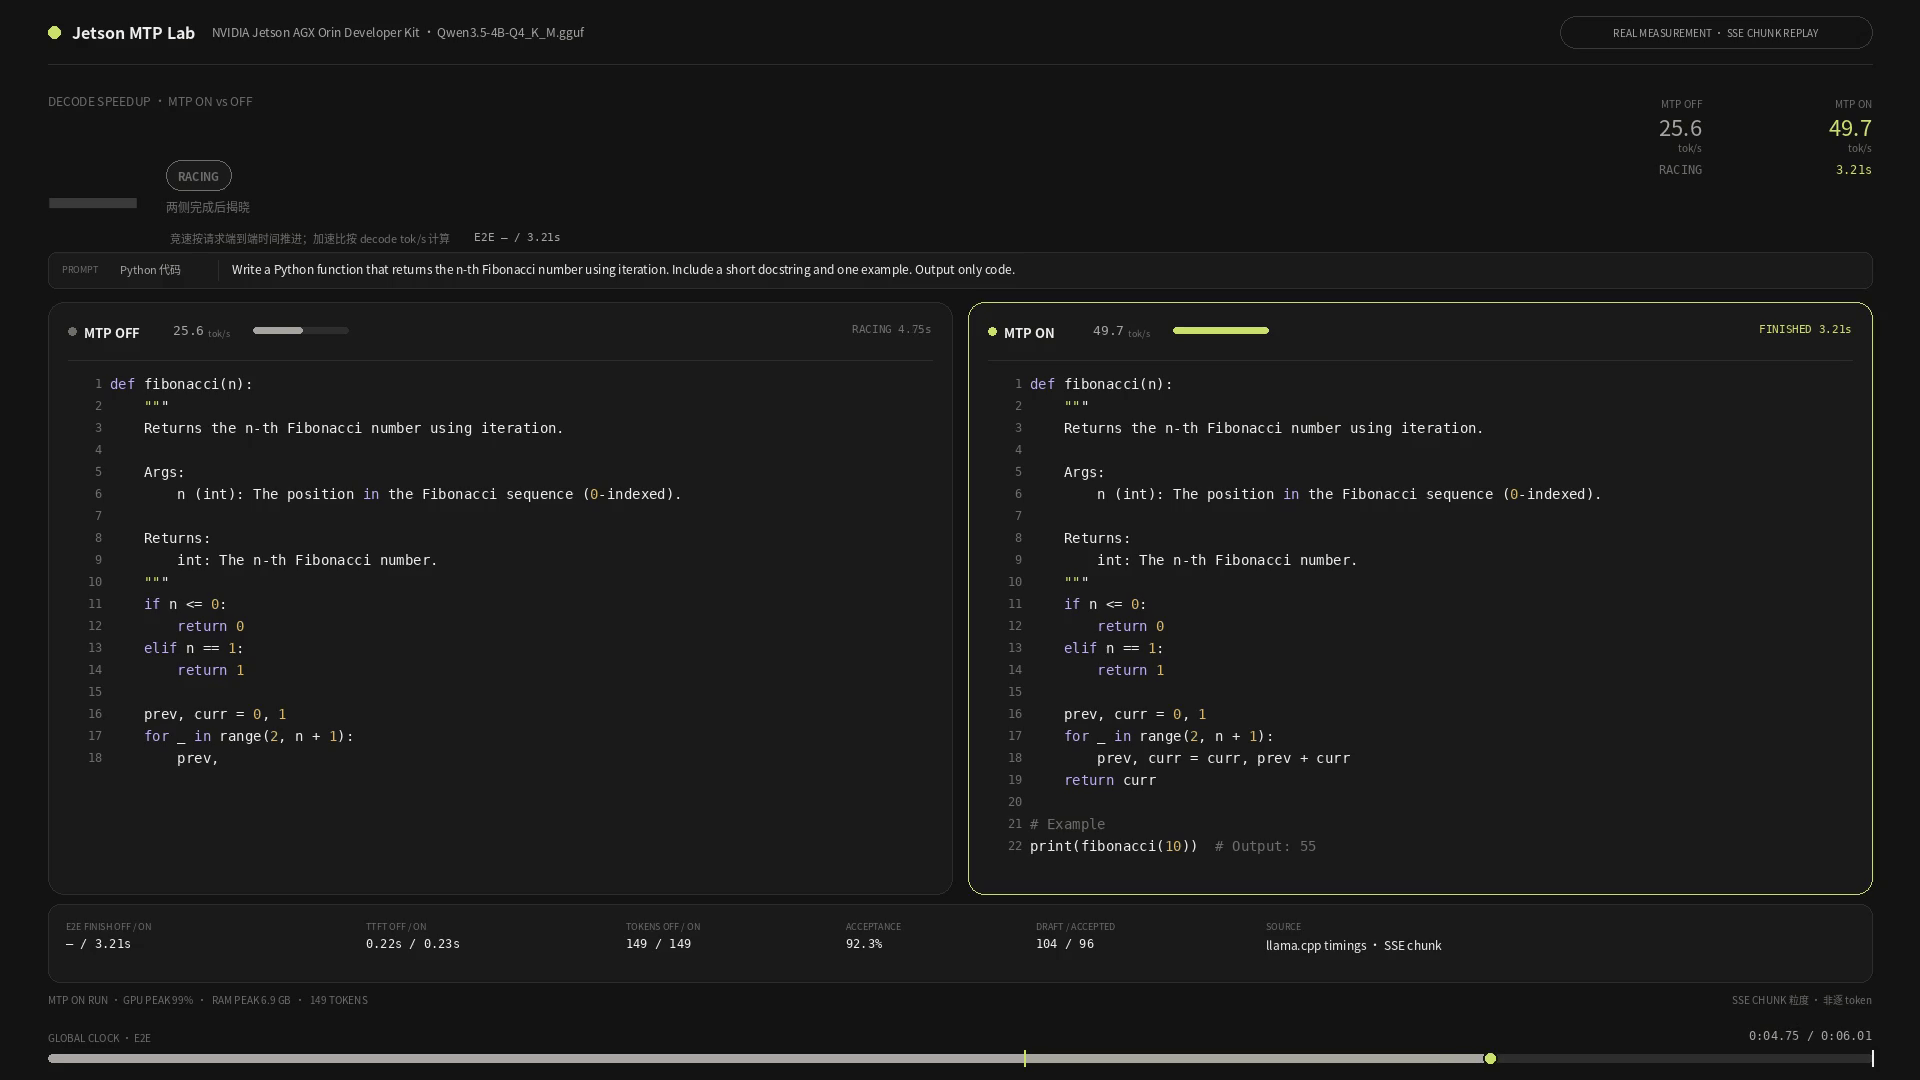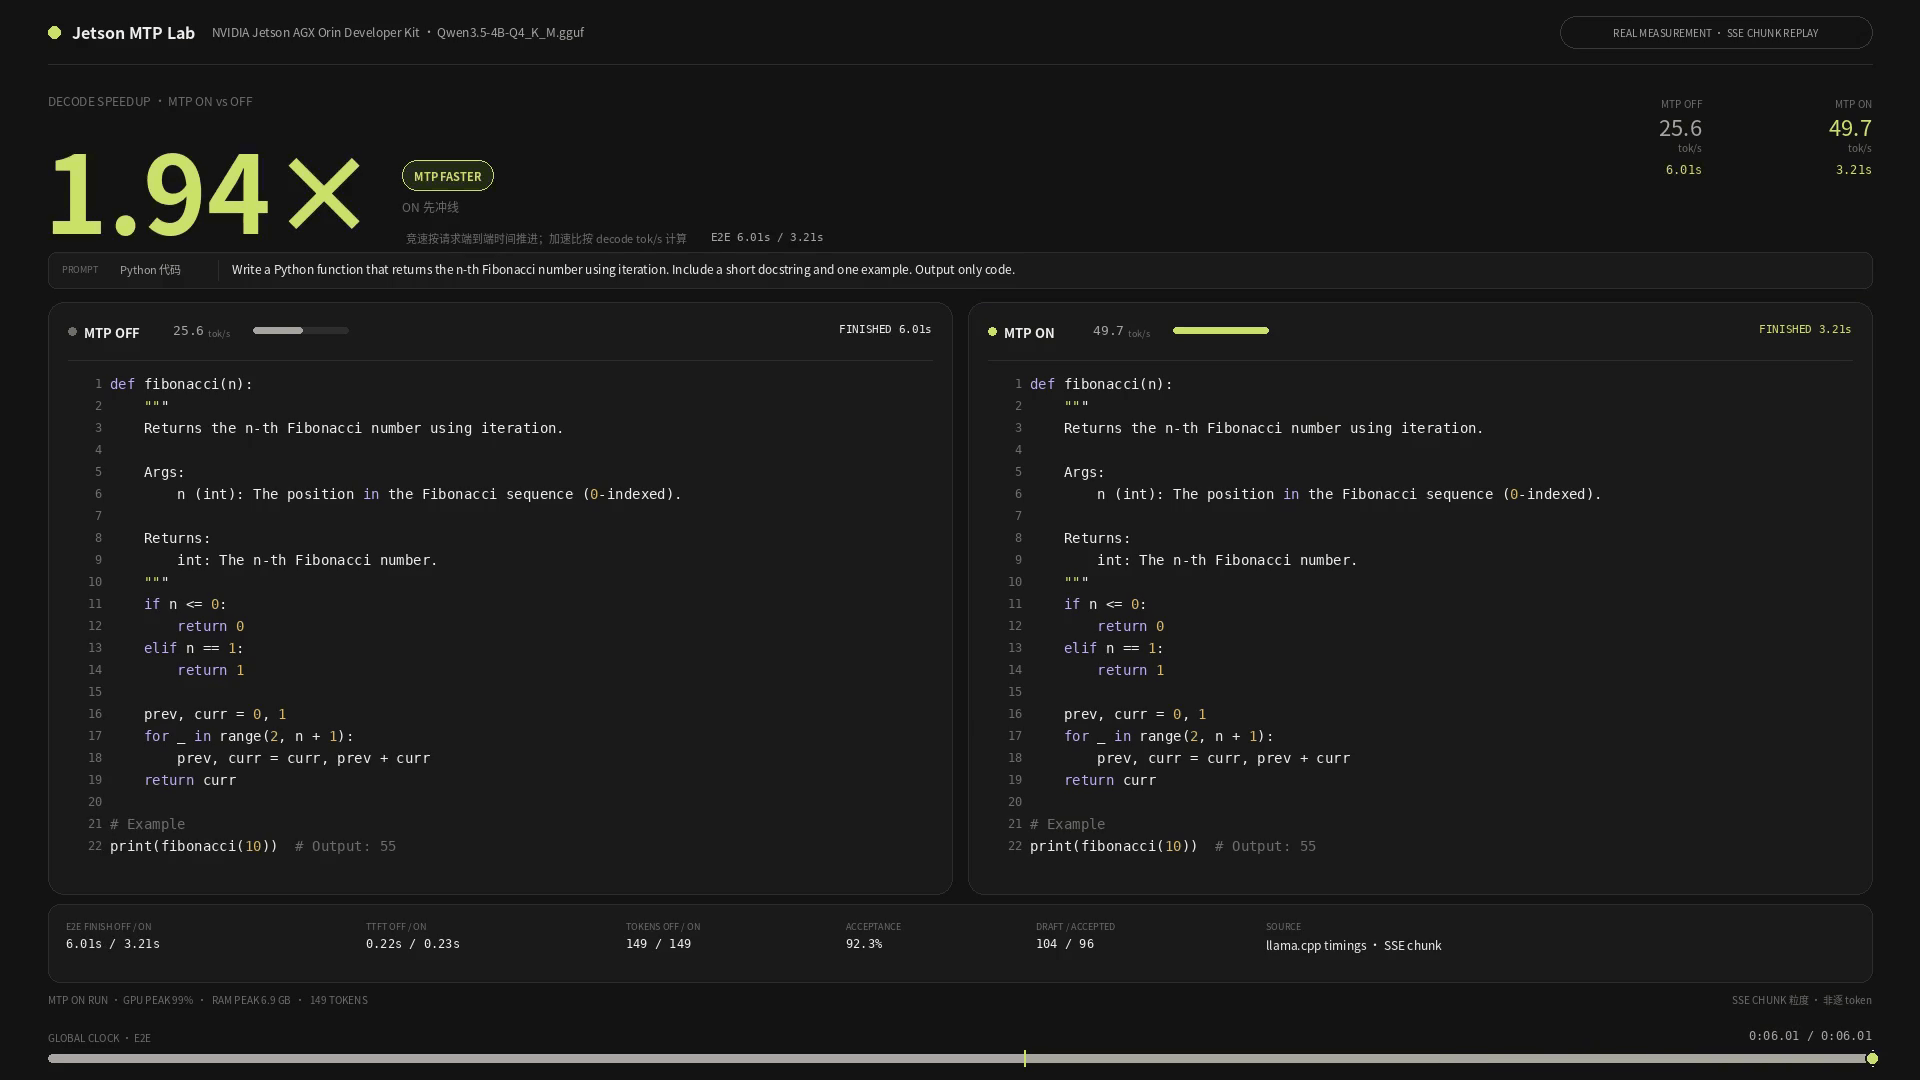
+ MTP OFF on the left and MTP ON on the right generating Fibonacci code with Qwen3.5-4B on Jetson AGX Orin. +
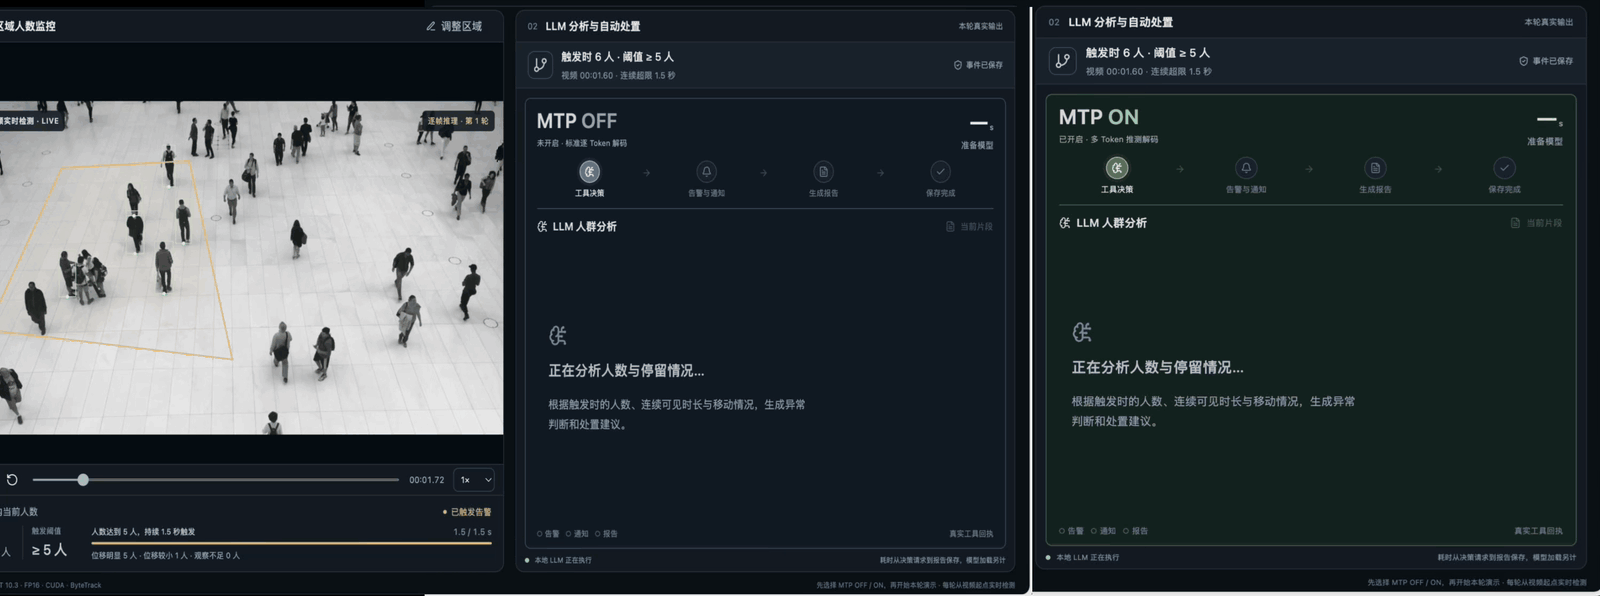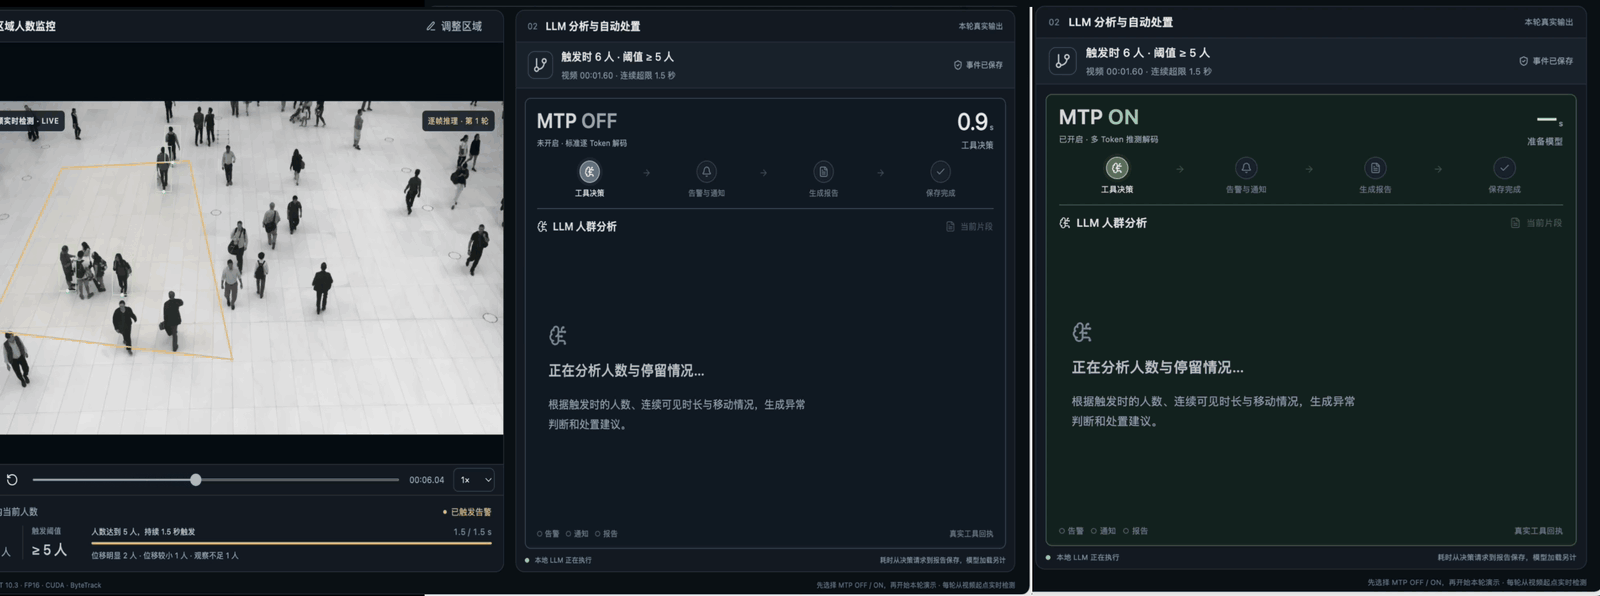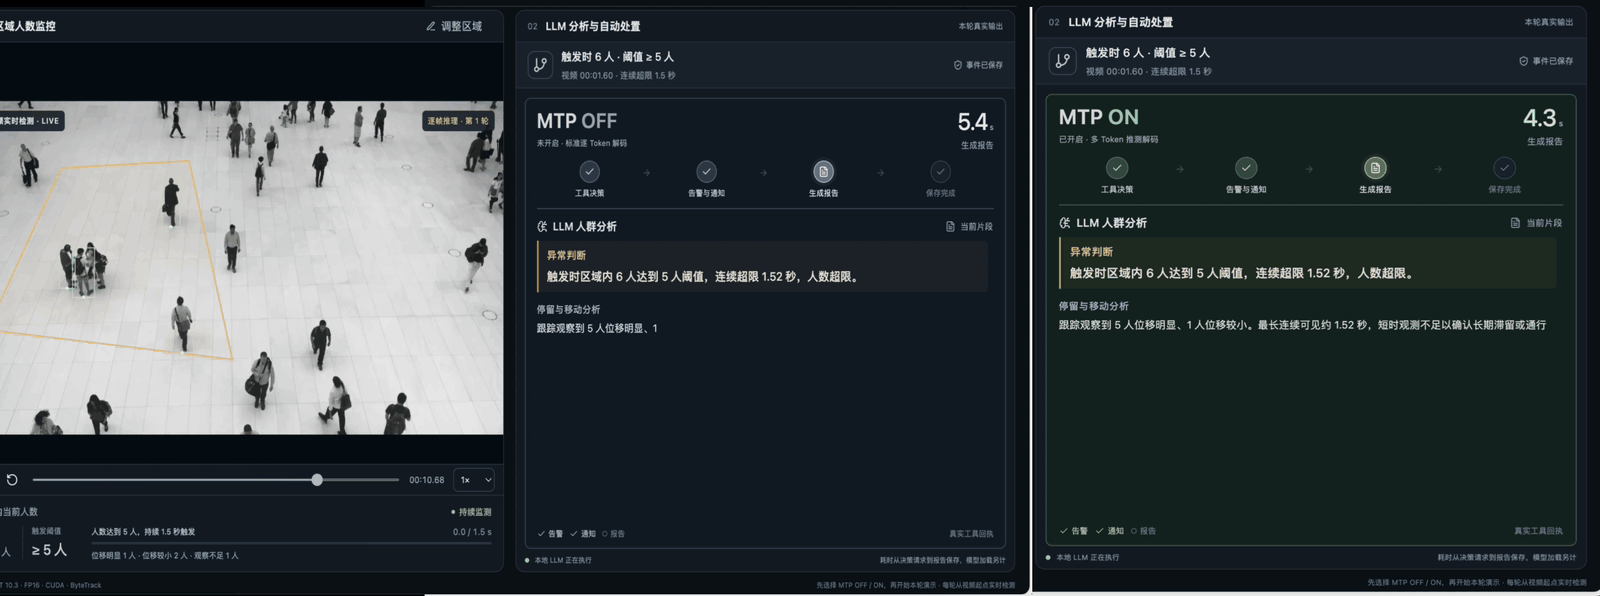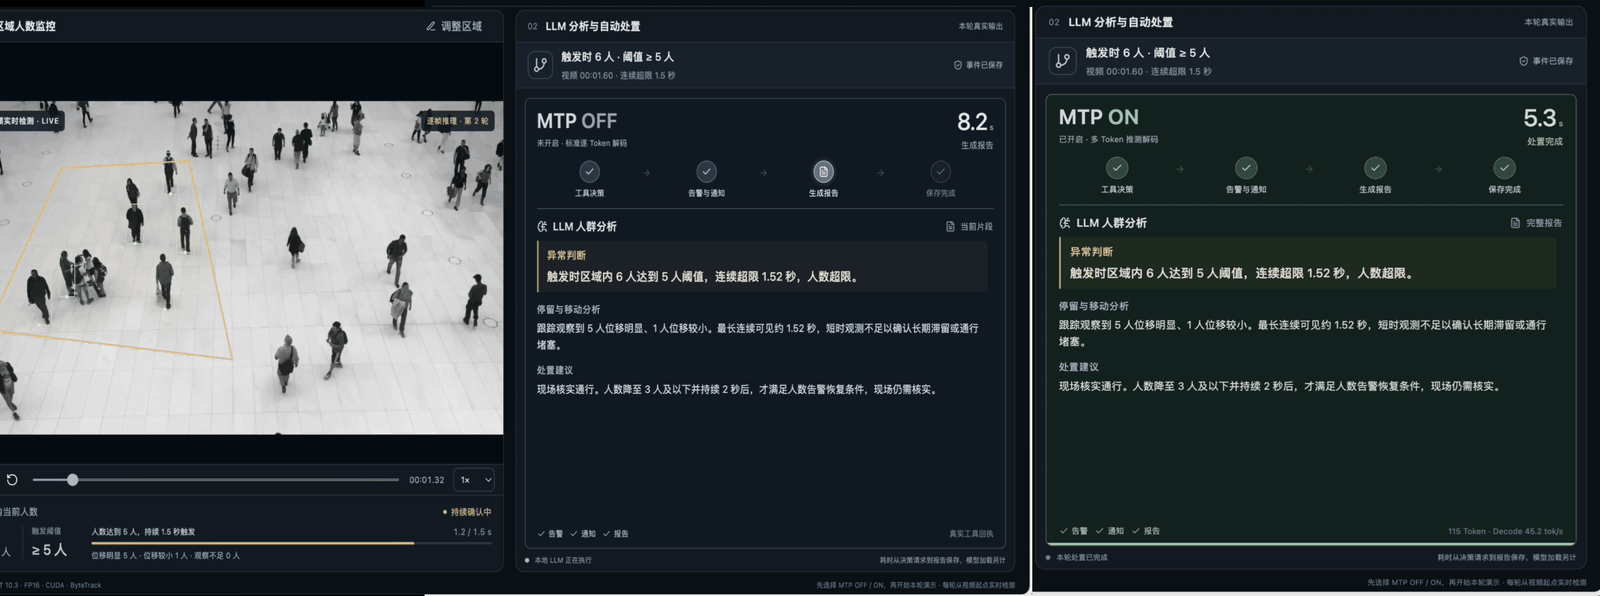
+ +Without MTP mode enabled, the Qwen3.5 4B model outputs tokens at a rate of about 25.6 tokens/s, whereas with MTP mode enabled, the same model on the same device reaches a generation speed of 49.7 tokens/s. It can be seen that for this kind of relatively deterministic content, the model's generation speed nearly doubles. This gives us some insight: for some relatively routine tasks, enabling MTP mode can bring decent performance improvement gains! + +Look at another visual analysis scenario: define an ROI region, and monitor whether the ROI count stays at or above five people for 1.5 seconds; if so, call the LLM for anomaly analysis and diagnosis. Let’s see how much faster it is with MTP mode enabled in the visual analysis scenario! + +
+ Video-based ROI tracking on the left, with MTP OFF and ON crowd-analysis results in the center and right panels. +
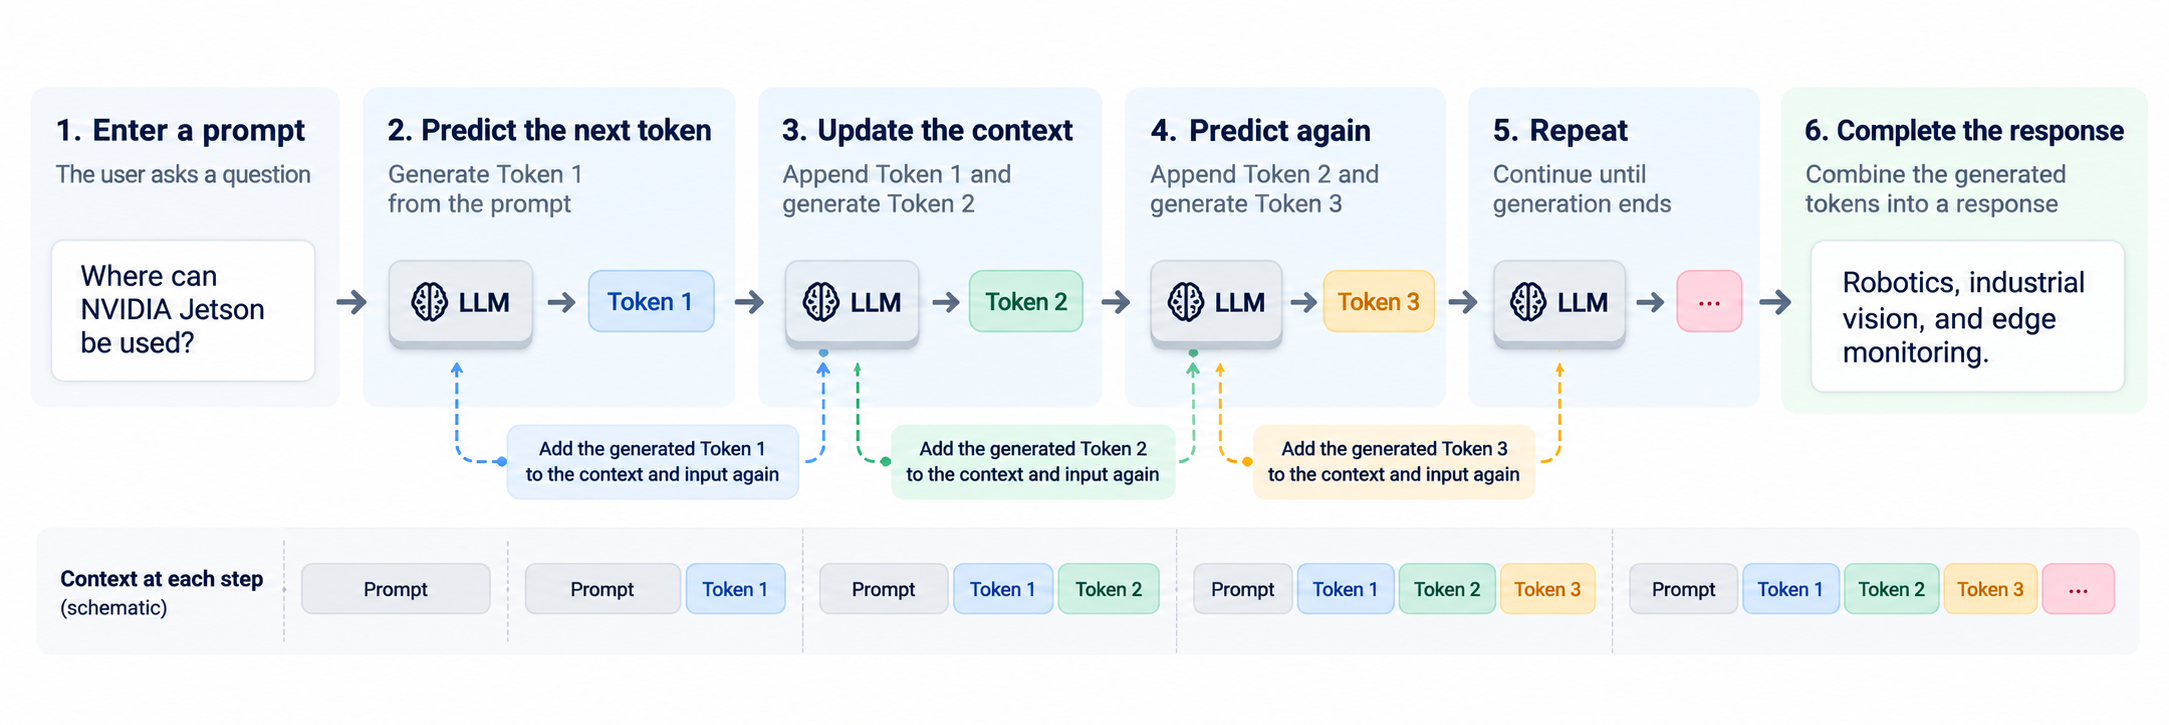
+ +As can be seen, for the above scenario, enabling MTP mode can shorten our task completion time by about 3 seconds—this optimization is quite significant! + + + +## Why Does LLM Text Generation Take Time? + +### One token at a time + +Ask a model where NVIDIA Jetson can be used, and it may answer with robotics, industrial vision, and edge monitoring. The sentence appears gradually because an autoregressive LLM predicts one token, adds it to the context, and uses that context to predict the next. + +A token may be a word, part of a word, or a punctuation mark. Each new prediction depends on what came before it, so the model repeats this process until the response is complete. + +
+ Autoregressive decoding adds each generated token to the context before predicting the next. +
+ +At 20 tokens/s, generating 500 tokens takes about 25 seconds of decode time. That wait becomes noticeable when a local assistant writes code or a report. + +### Prefill and decode + +LLM inference has two main stages. + +| Stage | Main task | Characteristic | +| --- | --- | --- | +| Prefill | Read the prompt and build context state | Input positions can be processed in parallel | +| Decode | Generate the response | Later tokens depend on earlier output | + +
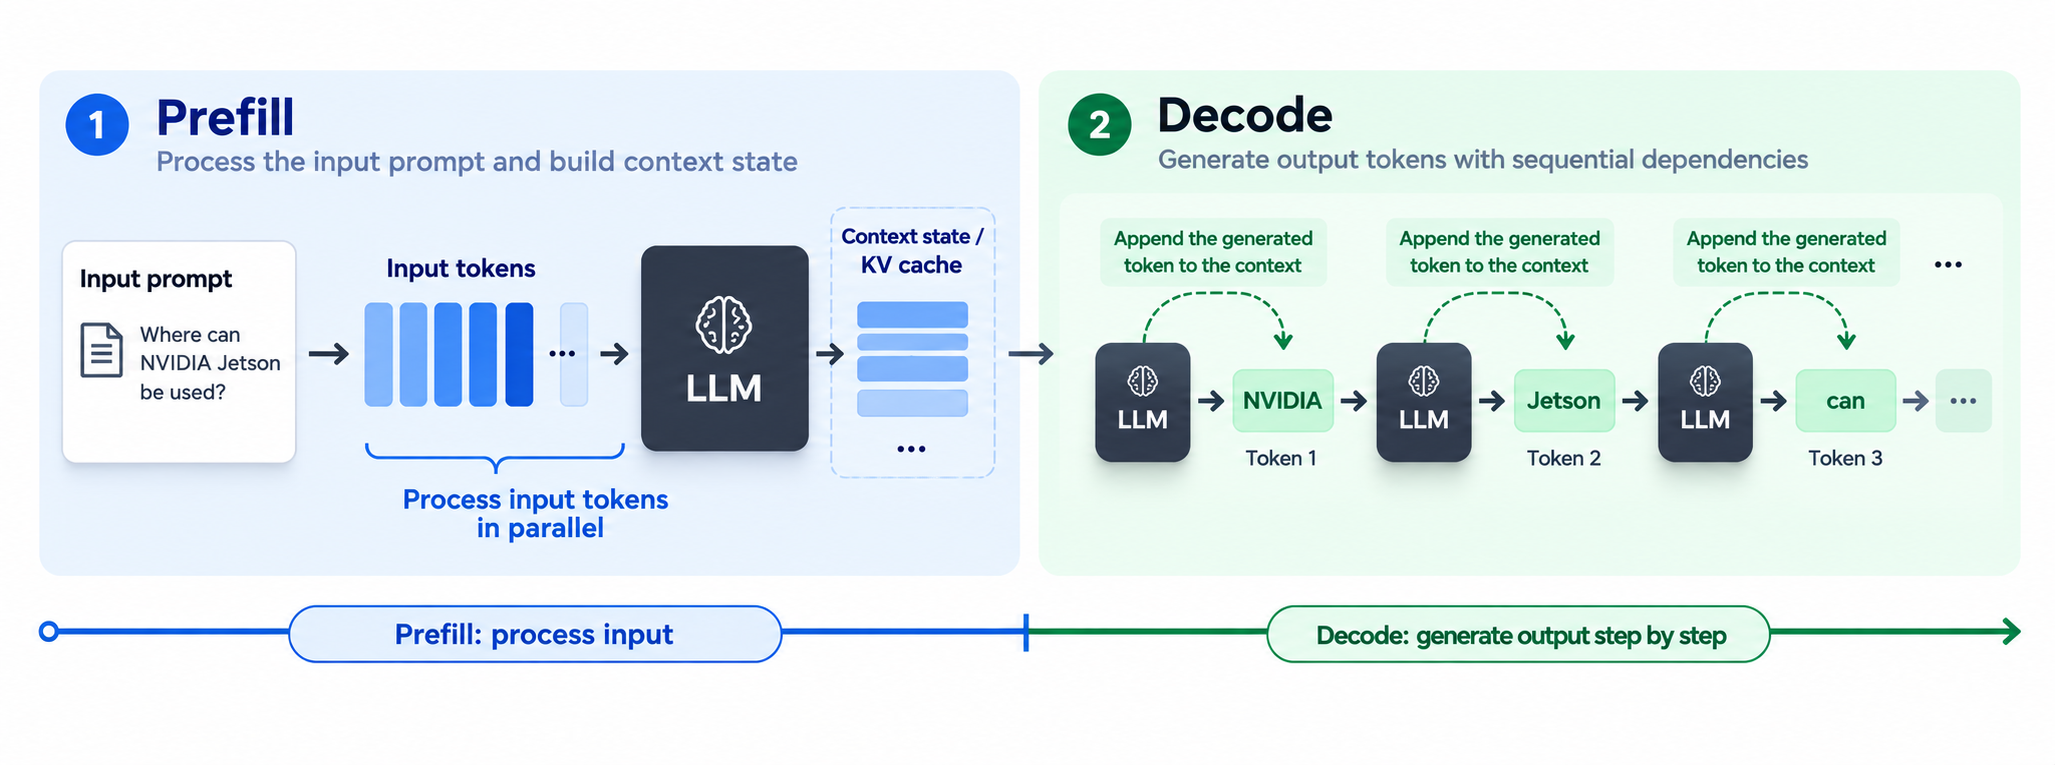
+ Prefill processes the prompt on the left; decode generates output tokens step by step on the right. +
+ +For a single-user LLM on Jetson, decode often spends much of its time reading model weights and cached context from memory. The GPU has parallel computing capacity, but a sequence of single-token steps may make limited use of it. MTP primarily targets this decode stage. + +## What Is Multi-Token Prediction? + +Multi-Token Prediction trains additional prediction heads or layers to propose future tokens. These candidates can then be used in speculative decoding, where the target model verifies several positions together before accepting output. + +
+ Standard decoding on the left; MTP candidate drafting and target-model verification on the right. +
+ +When several candidates pass verification, the response advances by multiple tokens in one target-model pass. If a candidate fails, the runtime keeps the accepted prefix and discards the rejected candidate and remaining draft. The target model continues from that point. + +This reduces the number of serial decoding passes when the proposals are accurate enough. The target model still checks the output. Correct lossless speculative decoding preserves its greedy result or sampling distribution, although quantization and runtime numerical differences can affect practical behavior. + +The [multi-token prediction paper](https://arxiv.org/abs/2404.19737) explains the training idea. The [llama.cpp speculative decoding documentation](https://github.com/ggml-org/llama.cpp/blob/master/docs/speculative.md) describes its use during inference. + +## Why Can MTP Be Faster? + +### More useful output per verification + +Batch verification lets the target model check several candidates together. In a memory-bandwidth-limited workload, that can cost less than generating the same tokens through separate serial passes. + +Drafting and verification also take time. MTP speeds up generation only when the saved work exceeds this extra cost. A useful diagnostic is the draft acceptance rate, calculated as accepted draft tokens divided by generated draft tokens. Also measure how far each verification advances the response and how long the complete request takes. + +### Draft depth needs testing + +The maximum draft length is controlled by `--spec-draft-n-max`. A longer draft gives the target model more candidates to check, but later candidates may be less accurate. Discarding them can outweigh the benefit of a larger batch. + +Start with a small depth and compare it on your own prompts. The Edge Crowd Agent comparison uses depth 2. A setting that works well for regular code or report formats may behave differently on another workload. + +## Enable MTP in llama.cpp on Jetson + +The demonstrations use the following setup. + +| Component | Configuration | +| --- | --- | +| Hardware | NVIDIA Jetson AGX Orin 32GB | +| JetPack | 6.2.1 | +| Runtime | llama.cpp with CUDA | +| Model | Qwen3.5-4B with MTP tensors | +| Quantization | Q4_K_M GGUF | +| Comparison | MTP OFF / MTP ON | + +Build llama.cpp with CUDA by following the [official build instructions](https://github.com/ggml-org/llama.cpp/blob/master/docs/build.md). Choose the [MTP-enabled Qwen3.5-4B GGUF](https://huggingface.co/unsloth/Qwen3.5-4B-MTP-GGUF), and check that your binary's help output lists `draft-mtp`. + +Once the runtime is ready, the MTP launch command is short. + +```bash +llama-server \ + -hf unsloth/Qwen3.5-4B-MTP-GGUF:Q4_K_M \ + -ngl 99 -c 8192 -np 1 \ + --spec-type draft-mtp \ + --spec-draft-n-max 2 +``` + +Use the `llama-server` binary from your build. For a downloaded model, replace `-hf` with `-m` followed by the local GGUF path. + +`--spec-type draft-mtp` enables MTP; `--spec-draft-n-max` controls its depth. For the OFF comparison, use `--spec-type none` and keep the model and shared settings unchanged. + +After generation, check the startup log for the loaded MTP tensors and the server's draft acceptance statistics. Use one slot and text-only requests for this setup; consult the [model publisher's instructions](https://huggingface.co/unsloth/Qwen3.5-4B-MTP-GGUF) for current compatibility restrictions. + + +## Where Is MTP Useful? + +### Inspection and monitoring reports + +A Jetson can collect detections, sensor readings, and equipment logs, then ask a local LLM to write an inspection report. Recurring fields and descriptions make this a useful workload for testing candidate acceptance. The benefit is a shorter wait for the written report; real-time control and protection remain separate. + +### Local coding assistants + +Python scripts, shell commands, and device configuration files often produce relatively long responses with regular syntax. The Fibonacci example in the Introduction shows the potential on this device. Generated code still needs to be checked and tested. + +### Offline voice assistants and robots + +A voice assistant passes recognized speech to the local LLM, then sends its response to text-to-speech. + +
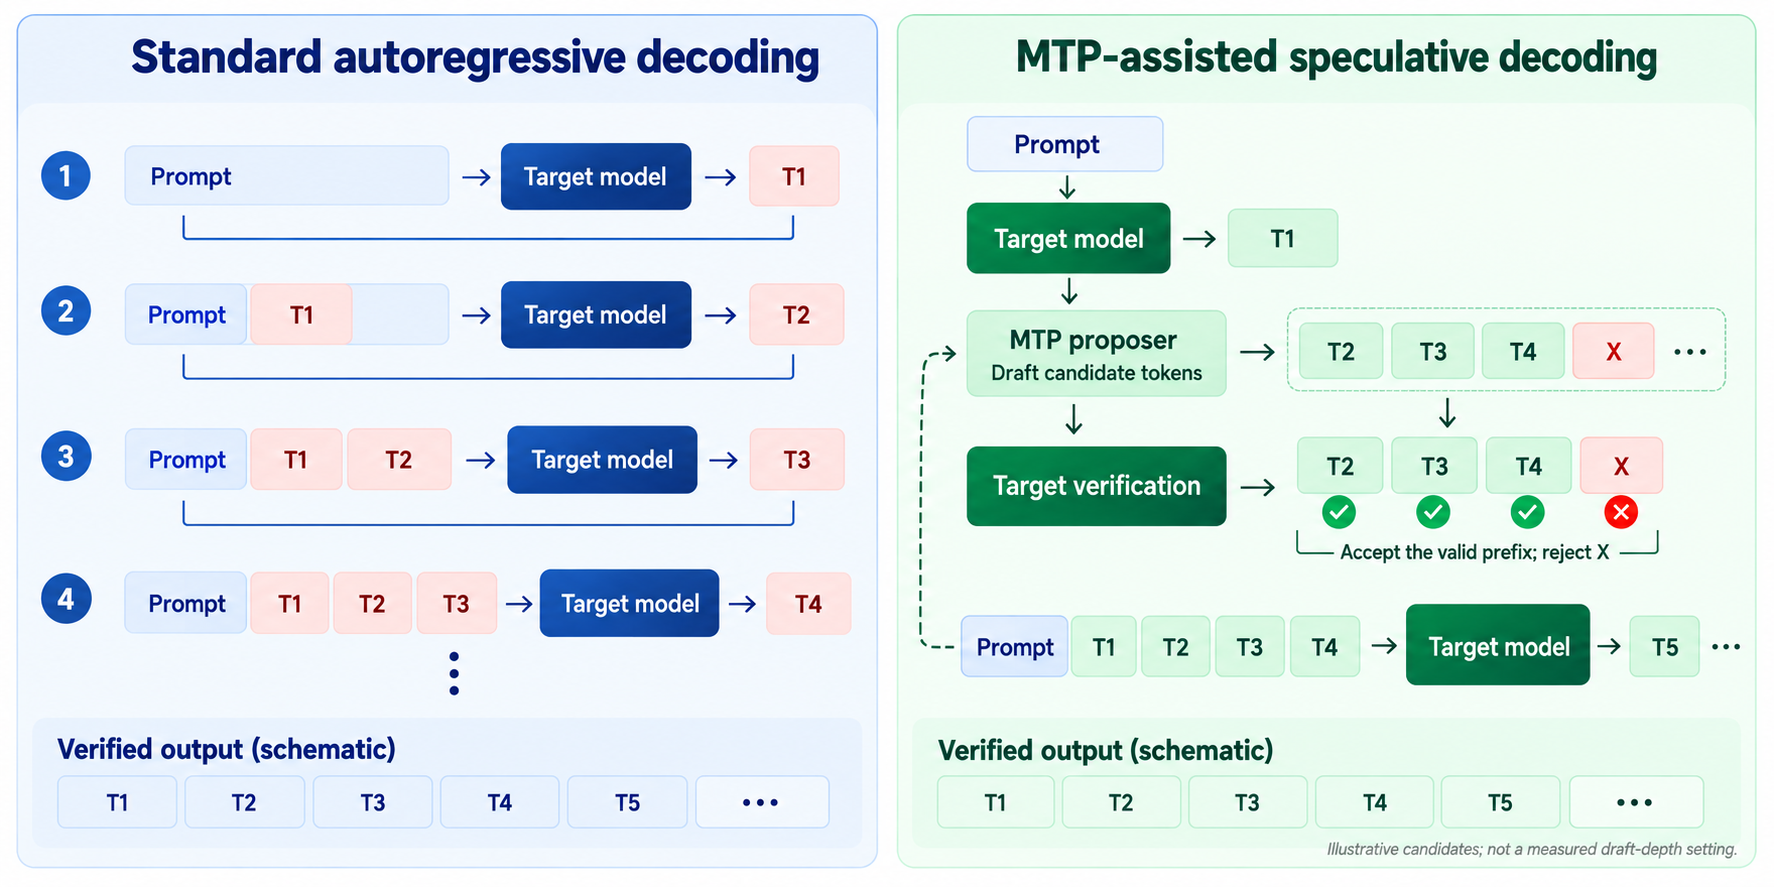
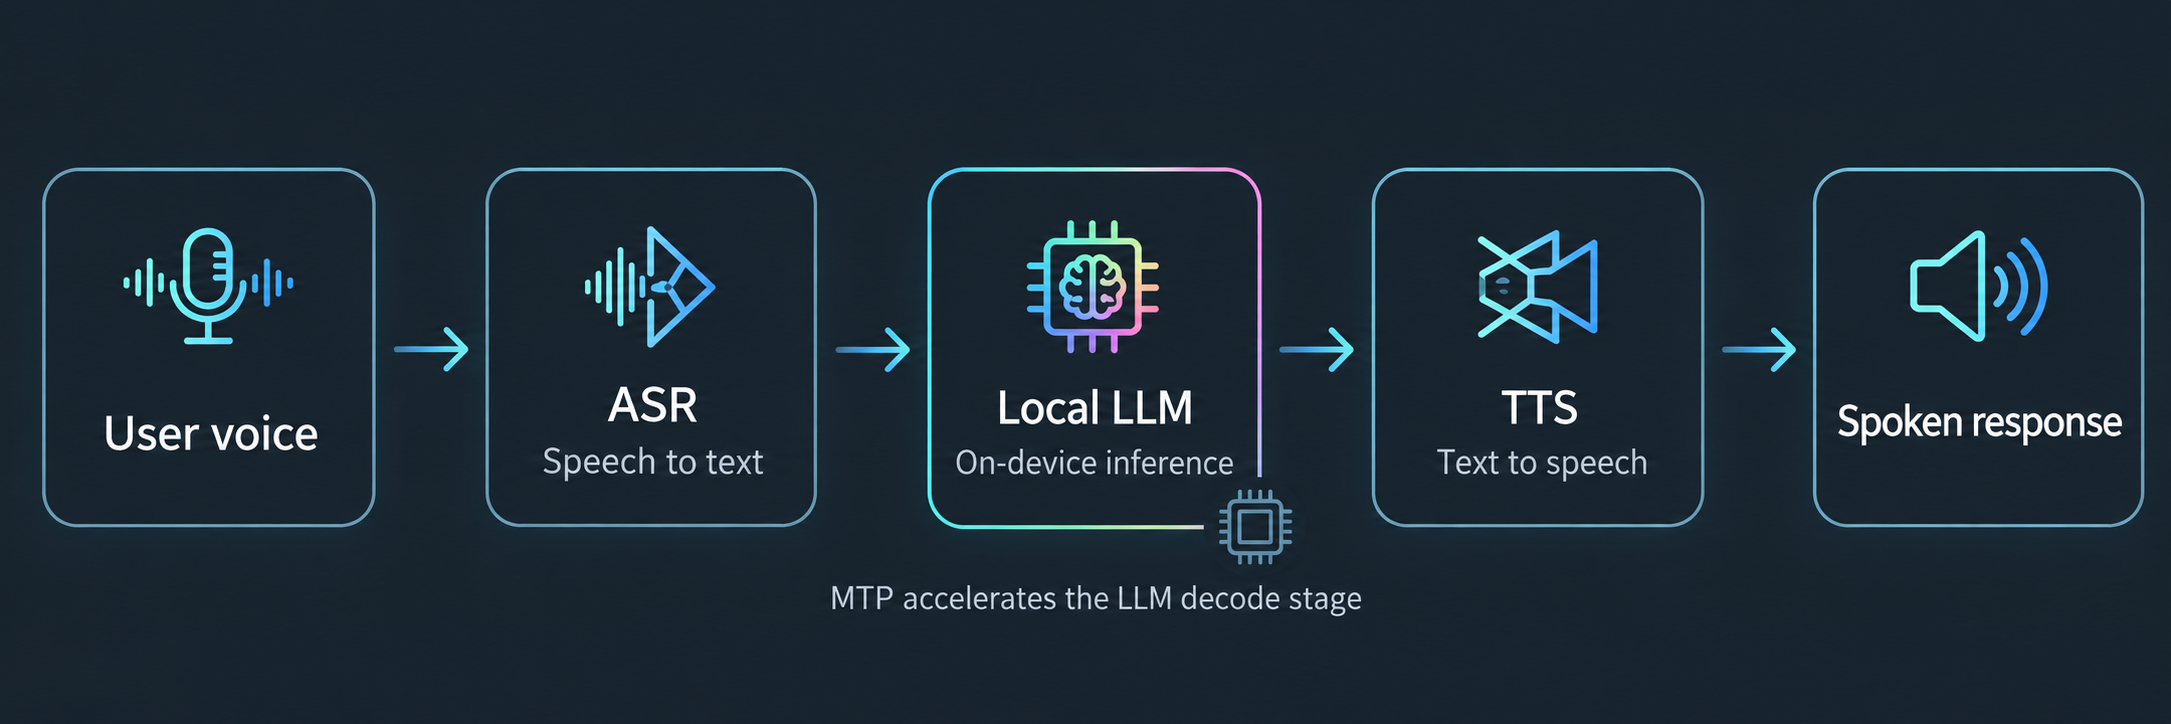
+ Voice-assistant pipeline from speech recognition through a local LLM to speech synthesis. +
+ +MTP can shorten the LLM's decode stage for longer replies. Speech recognition, synthesis, and streaming determine when the user actually hears an answer, so measure time to first usable speech as well as full response time. + +### Local knowledge and technical explanations + +Troubleshooting instructions and long answers based on device logs can spend substantial time generating output. These are worth testing. For a long document that needs only a one-line answer, prompt processing may dominate and leave little decode time to save. + +## When Is MTP Worth Enabling? + +A compatible model is the first requirement. The runtime must support its prediction components, and the extra drafting work must pay for itself on your hardware and prompts. Higher acceptance and longer outputs often help, while low acceptance or very short replies can make MTP slower. + +Compare the time your application actually needs. Faster decode does not shorten image processing, tool execution, or model loading by the same factor. Keep the model, input, output limits, and sampling settings consistent, then decide from the measured result. + +## Try the Crowd-Monitoring Demo + +
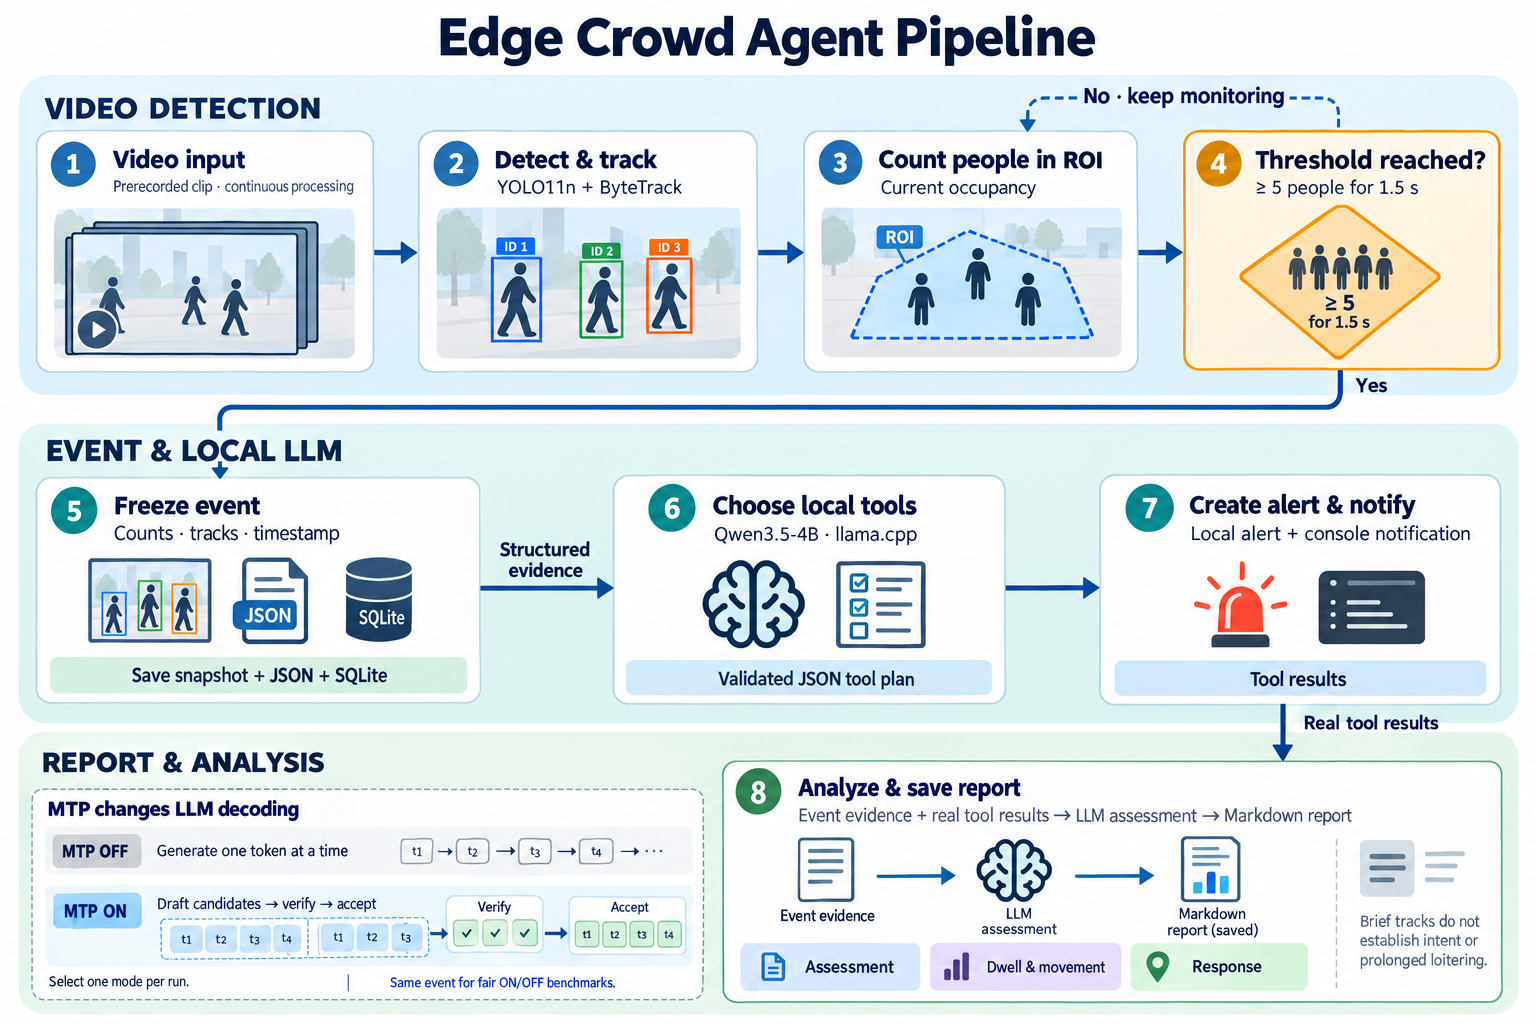
+ Edge Crowd Agent pipeline from video detection and ROI alerts to local LLM tools and reports, with MTP ON/OFF decoding. +
+ +The source for the opening demonstration is [Edge Crowd Agent](https://github.com/zibochen6/edge-crowd-agent). YOLO11n and ByteTrack measure current ROI occupancy, and a local LLM explains the saved count and movement evidence when an event is triggered. + +Follow **[Start on Jetson in the README](https://github.com/zibochen6/edge-crowd-agent#start-on-jetson)** for dependencies, model and video paths, environment checks, and startup. The project uses uv with system Python 3.10 to retain access to JetPack's TensorRT bindings. + +After startup, choose MTP OFF or ON and select **Start demo**. Video detection stays on the left, with analysis and tool progress on the right. The [recording guide](https://github.com/zibochen6/edge-crowd-agent#record-off-and-on) explains how to run both demonstrations. + +
+ Video-based ROI tracking on the left, with MTP OFF and ON crowd-analysis results in the center and right panels. +
+ +The default event condition is at least 5 people in the ROI for 1.5 seconds of continuous video time. The LLM receives structured evidence rather than video pixels; brief tracks support an occupancy assessment, but cannot establish intent or prolonged loitering. + +For a controlled comparison, use the same frozen event rather than two separate recordings. The README's [benchmark section](https://github.com/zibochen6/edge-crowd-agent#benchmarks-and-measured-latency) provides the test method and measured results, with model loading listed separately. + +## References + +- [Edge Crowd Agent source and usage](https://github.com/zibochen6/edge-crowd-agent) +- [Edge Crowd Agent benchmark records](https://github.com/zibochen6/edge-crowd-agent/blob/main/docs/measurements/behavior-v3-fast.json) +- [Jetson AI Lab speculative decoding tutorial](https://www.jetson-ai-lab.com/tutorials/speculative-decoding/) +- [llama.cpp speculative decoding documentation](https://github.com/ggml-org/llama.cpp/blob/master/docs/speculative.md) +- [llama.cpp SPEED-Bench](https://github.com/ggml-org/llama.cpp/tree/master/tools/server/bench/speed-bench) +- [Qwen3.5-4B MTP GGUF model](https://huggingface.co/unsloth/Qwen3.5-4B-MTP-GGUF) +- [Better & Faster Large Language Models via Multi-token Prediction](https://arxiv.org/abs/2404.19737) + +## Tech Support & Product Discussion + +Thank you for choosing our products! We are here to provide you with different support to ensure that your experience with our products is as smooth as possible. We offer several communication channels to cater to different preferences and needs. + +
+ + +
+ +
+ + +
diff --git a/sites/en/jetson-sidebar.js b/sites/en/jetson-sidebar.js index b8b6a5bbcaaa91..ee6c69e6c485e6 100644 --- a/sites/en/jetson-sidebar.js +++ b/sites/en/jetson-sidebar.js @@ -410,6 +410,7 @@ const sidebars = { label: 'Generative AI', customProps: { communityCategory: 'gen' }, items: [ + 'Edge/NVIDIA_Jetson/Application/Generative_AI/Accelerate_LLM_Inference_with_MTP_on_Jetson', 'Edge/NVIDIA_Jetson/Application/Generative_AI/Finetune_LLM_by_Llama_Factory_on_Jetson', 'Edge/NVIDIA_Jetson/Application/Generative_AI/Whisper_on_Jetson_for_Real_Time_Speech_to_Text', 'Edge/NVIDIA_Jetson/Application/Generative_AI/Local_RAG_based_on_Jetson_with_LlamaIndex', diff --git a/static/img/jetson-mtp-draft/README.md b/static/img/jetson-mtp-draft/README.md new file mode 100644 index 00000000000000..a1a58aea160612 --- /dev/null +++ b/static/img/jetson-mtp-draft/README.md @@ -0,0 +1,45 @@ +# English artwork review — local Wiki draft + +Prepared on October 23, 2026 using the built-in imagegen editing tool. These five English PNGs are local source copies of the uploaded article artwork. The original source images and the two GIFs have not been changed. Exact editing prompts are recorded in `english-image-prompts.json`. + +| English asset | Review and correction | +| --- | --- | +| `jetson-mtp-cover-en.png` | All Chinese display text translated. Removed the original J501 label to avoid implying that the illustrated enclosure identifies the measured AGX Orin 32GB device. Preserved the illustration and NVIDIA Jetson branding. | +| `autoregressive-token-generation-en.png` | English headings, prompt, annotations, context timeline, and example response. Uses schematic Token 1/2/3 labels instead of suggesting complete English words are always one token. Checked left-to-right progression and context feedback. | +| `prefill-vs-decode-en.png` | English headings and annotations; parallel input processing is distinct from sequential output generation. Example word boundaries remain schematic, as the figure caption states. Checked arrow and cache labels. | +| `autoregressive-vs-mtp-en.png` | English labels; the proposer produces candidates, target verification accepts T2–T4 and rejects X, and only accepted tokens enter the context. Matching output rows are schematic. The illustration explicitly does not specify the measured draft depth, which is 2. | +| `jetson-voice-assistant-pipeline-en.png` | English labels for user voice, ASR, local LLM, TTS, and spoken response. Annotation locates MTP at the LLM decode stage, without implying acceleration of ASR or TTS. | + +All five outputs were visually inspected for remaining Chinese text, English spelling, clipped labels, diagram direction, and consistency with the article. All five article image tags include descriptive English alt text. Any illustrative acceleration wording describes the intended stage, not a guaranteed speedup for every workload. + +The GIF files were not edited. The article uses uploaded `mtp_vs.gif` and `mtp_demo.gif` in the Introduction. Their alt text was checked against the middle and final frames. This folder includes no copied GIF. + +Keep this review and prompts separate from the article. The article remains a local draft; publication is a separate action. + +## Editorial asset checklist + +The English static PNGs are stored under `static/img/jetson-mtp-draft/` in this checkout. Original PNGs and GIFs remain unchanged in the source note's `Tmp/images/` folder. The article now uses uploaded PNGs and GIFs under `https://files.seeedstudio.com/wiki/Jetson/Application/`. The English editing review and prompts are saved with the local artwork. + +| Asset / position | Original source filename | Uploaded filename | English alt text | +| --- | --- | --- | --- | +| 1 / Introduction | `Pasted image 20261023105746.png` | `jetson-mtp-cover-en.png` | NVIDIA Jetson illustration with Qwen3.5-4B, llama.cpp, and an MTP token-flow graphic. | +| 2 / Autoregressive generation | `Pasted image 20261021111409.png` | `autoregressive-token-generation-en.png` | Autoregressive decoding adds each generated token to the context before predicting the next. | +| 3 / Prefill and decode | `Pasted image 20261021113558.png` | `prefill-vs-decode-en.png` | Prefill processes the prompt on the left; decode generates output tokens step by step on the right. | +| 4 / MTP verification | `Pasted image 20261022110151.png` | `autoregressive-vs-mtp-en.png` | Standard decoding on the left; MTP candidate drafting and target-model verification on the right. | +| 5 / Code demonstration | `jetson-mtp-lab-20261022-110633-200af2.gif` | `mtp_vs.gif` | MTP OFF on the left and MTP ON on the right generating Fibonacci code with Qwen3.5-4B on Jetson AGX Orin. | +| 6 / Crowd demonstration | `mtp demo (1600px) 1.gif` | `mtp_demo.gif` | Video-based ROI tracking on the left, with MTP OFF and ON crowd-analysis results in the center and right panels. | +| 7 / Voice use case | `Pasted image 20261023094537.png` | `jetson-voice-assistant-pipeline-en.png` | Voice-assistant pipeline from speech recognition through a local LLM to speech synthesis. | + +The Introduction holds both demo GIFs. Duplicate placeholders and all visible Figure captions have been removed. GIF translation remains deferred; files and image order were preserved. + +## Prose and accessibility revision + +The article now uses the title `Speed Up llama.cpp on NVIDIA Jetson AGX Orin with MTP`. The slug remains `/jetson/accelerate_llm_inference_mtp`. All seven alt descriptions were shortened to describe the image rather than repeat benchmark findings. Static artwork and GIF files were not edited in this revision. Code blocks and historical benchmark values were retained. + +## Current image audit + +All seven rendered image resources were checked. The five uploaded PNGs match the previously reviewed local English files byte for byte. The code GIF shows OFF on the left and ON on the right; the crowd GIF shows detection on the left, OFF analysis in the center, and ON analysis on the right. Each now has its own matching alt. No visible Figure captions remain. + +## Source-note structure revision + +The article follows the author's source-note structure: generation basics, MTP verification, acceleration and draft depth, a short enablement example, and practical applications. The author's Introduction and all seven image tags were preserved. Build steps now link to llama.cpp documentation; project setup, recording, and measurements link to README sections. Only one MTP launch code block remains. diff --git a/static/img/jetson-mtp-draft/autoregressive-token-generation-en.png b/static/img/jetson-mtp-draft/autoregressive-token-generation-en.png new file mode 100644 index 00000000000000..2b37e5ec2a9bf4 Binary files /dev/null and b/static/img/jetson-mtp-draft/autoregressive-token-generation-en.png differ diff --git a/static/img/jetson-mtp-draft/autoregressive-vs-mtp-en.png b/static/img/jetson-mtp-draft/autoregressive-vs-mtp-en.png new file mode 100644 index 00000000000000..c5532eeaad88d9 Binary files /dev/null and b/static/img/jetson-mtp-draft/autoregressive-vs-mtp-en.png differ diff --git a/static/img/jetson-mtp-draft/draft-validation.json b/static/img/jetson-mtp-draft/draft-validation.json new file mode 100644 index 00000000000000..e64196f5067c85 --- /dev/null +++ b/static/img/jetson-mtp-draft/draft-validation.json @@ -0,0 +1,94 @@ +{ + "date": "2026-10-23", + "revision": "Source-note style; documentation links instead of installation walkthroughs", + "title": "Speed Up llama.cpp on NVIDIA Jetson AGX Orin with MTP", + "description": "Enable Multi-Token Prediction in llama.cpp on NVIDIA Jetson AGX Orin. Follow Qwen3.5-4B setup steps and compare MTP ON/OFF benchmark results.", + "slug": "/jetson/accelerate_llm_inference_mtp", + "url": "https://wiki.seeedstudio.com/jetson/accelerate_llm_inference_mtp/", + "draft": true, + "author": "zibo", + "introduction_preserved": true, + "image_order_preserved": true, + "rendered_images": 7, + "images": [ + { + "url": "https://files.seeedstudio.com/wiki/Jetson/Application/jetson-mtp-cover-en.png", + "alt": "NVIDIA Jetson illustration with Qwen3.5-4B, llama.cpp, and an MTP token-flow graphic." + }, + { + "url": "https://files.seeedstudio.com/wiki/Jetson/Application/mtp_vs.gif", + "alt": "MTP OFF on the left and MTP ON on the right generating Fibonacci code with Qwen3.5-4B on Jetson AGX Orin." + }, + { + "url": "https://files.seeedstudio.com/wiki/Jetson/Application/mtp_demo.gif", + "alt": "Video-based ROI tracking on the left, with MTP OFF and ON crowd-analysis results in the center and right panels." + }, + { + "url": "https://files.seeedstudio.com/wiki/Jetson/Application/autoregressive-token-generation-en.png", + "alt": "Autoregressive decoding adds each generated token to the context before predicting the next." + }, + { + "url": "https://files.seeedstudio.com/wiki/Jetson/Application/prefill-vs-decode-en.png", + "alt": "Prefill processes the prompt on the left; decode generates output tokens step by step on the right." + }, + { + "url": "https://files.seeedstudio.com/wiki/Jetson/Application/autoregressive-vs-mtp-en.png", + "alt": "Standard decoding on the left; MTP candidate drafting and target-model verification on the right." + }, + { + "url": "https://files.seeedstudio.com/wiki/Jetson/Application/jetson-voice-assistant-pipeline-en.png", + "alt": "Voice-assistant pipeline from speech recognition through a local LLM to speech synthesis." + } + ], + "visible_figure_captions": 0, + "shell_blocks_syntax_checked": 1, + "mdx_compile": "passed", + "render": "Isolated server render; no full site build", + "word_count": 1783, + "link_checks": [ + { + "url": "https://arxiv.org/abs/2404.19737", + "status": 200 + }, + { + "url": "https://github.com/ggml-org/llama.cpp/blob/master/docs/speculative.md", + "status": 200 + }, + { + "url": "https://github.com/ggml-org/llama.cpp/blob/master/docs/build.md", + "status": 200 + }, + { + "url": "https://huggingface.co/unsloth/Qwen3.5-4B-MTP-GGUF", + "status": 200 + }, + { + "url": "https://github.com/zibochen6/edge-crowd-agent", + "status": 200 + }, + { + "url": "https://github.com/zibochen6/edge-crowd-agent#start-on-jetson", + "status": 200 + }, + { + "url": "https://github.com/zibochen6/edge-crowd-agent#record-off-and-on", + "status": 200 + }, + { + "url": "https://github.com/zibochen6/edge-crowd-agent#benchmarks-and-measured-latency", + "status": 200 + }, + { + "url": "https://github.com/zibochen6/edge-crowd-agent/blob/main/docs/measurements/behavior-v3-fast.json", + "status": 200 + }, + { + "url": "https://www.jetson-ai-lab.com/tutorials/speculative-decoding/", + "status": 200 + }, + { + "url": "https://github.com/ggml-org/llama.cpp/tree/master/tools/server/bench/speed-bench", + "status": 200 + } + ] +} diff --git a/static/img/jetson-mtp-draft/edge-crowd-agent-pipeline-en.alt.txt b/static/img/jetson-mtp-draft/edge-crowd-agent-pipeline-en.alt.txt new file mode 100644 index 00000000000000..028e944b0d5109 --- /dev/null +++ b/static/img/jetson-mtp-draft/edge-crowd-agent-pipeline-en.alt.txt @@ -0,0 +1 @@ +Edge Crowd Agent pipeline from video detection and ROI alerts to local LLM tools and reports, with MTP ON/OFF decoding. diff --git a/static/img/jetson-mtp-draft/edge-crowd-agent-pipeline-en.png b/static/img/jetson-mtp-draft/edge-crowd-agent-pipeline-en.png new file mode 100644 index 00000000000000..04dbb1deafdd41 Binary files /dev/null and b/static/img/jetson-mtp-draft/edge-crowd-agent-pipeline-en.png differ diff --git a/static/img/jetson-mtp-draft/edge-crowd-agent-pipeline-en.prompt.txt b/static/img/jetson-mtp-draft/edge-crowd-agent-pipeline-en.prompt.txt new file mode 100644 index 00000000000000..d533396793b501 --- /dev/null +++ b/static/img/jetson-mtp-draft/edge-crowd-agent-pipeline-en.prompt.txt @@ -0,0 +1,43 @@ +Create one polished, accurate English technical pipeline infographic for a Seeed Studio Wiki article about Edge Crowd Agent on NVIDIA Jetson AGX Orin. This is a STATIC EXPLANATORY DIAGRAM, not a screenshot and not a performance chart. Wide landscape canvas around 1800x1200, crisp readable text, generous whitespace. White / very pale blue background, dark navy text, restrained teal-blue accents, amber for the trigger and green for saved outputs. Modern flat rounded cards with clear arrows, small camera/person/ROI/database/brain/report line icons. Professional documentation style, no 3D, no photorealism, no fake console, no company logos. + +Exact title at top: "Edge Crowd Agent Pipeline". +Build a very clear THREE-ROW top-to-bottom pipeline, with each row read left to right. Use stage numbers 1 to 8. Layout and connections: +ROW 1 (label "VIDEO DETECTION") contains four cards across: +1 "Video input", secondary "Prerecorded clip · continuous processing", icon video with walking-person outlines. +arrow -> +2 "Detect & track", secondary "YOLO11n + ByteTrack", icon bounding boxes and track IDs. +arrow -> +3 "Count people in ROI", secondary "Current occupancy", icon polygon with three person markers. +arrow -> +4 "Threshold reached?", secondary "≥ 5 people for 1.5 s", amber diamond or amber-tinted card. +A small dashed loop FROM card 4 back toward card 3, with label "No · keep monitoring". A solid arrow exits card 4 downward labeled "Yes". + +ROW 2 (label "EVENT & LOCAL LLM") uses a clear left-to-right sequence of three larger cards with generous room: +5 "Freeze event", secondary "Counts · tracks · timestamp", and a small lower line "Save snapshot + JSON + SQLite". +arrow labeled "Structured evidence" -> +6 "Choose local tools", secondary "Qwen3.5-4B · llama.cpp", small label "Validated JSON tool plan". +arrow -> +7 "Create alert & notify", secondary "Local alert + console notification", small tag "Tool results". +Make the Yes connector from the row-1 threshold card route outside the right edge of the row, then across a reserved empty corridor between rows and into the LEFT input of card 5. No connector should cross a card, label, or another edge. Make arrow direction unambiguous. + +ROW 3 has the final stage in a wide central panel: +8 "Analyze & save report", secondary "Event evidence + real tool results → LLM assessment → Markdown report". +Connect card 7 downward to stage 8 with an arrow labeled "Real tool results". Add three small readable report section chips inside stage 8: "Assessment", "Dwell & movement", "Response". Add one tiny unobtrusive note beside the output: "Brief tracks do not establish intent or prolonged loitering." + +Add a tasteful compact TWO-MODE INSET attached visually to the LLM region (cards 6 and 8), not to video detection. Heading "MTP changes LLM decoding". Two parallel illustrative mini-rows: +"MTP OFF" followed by "Generate one token at a time" and a simple serial token sequence. +"MTP ON" followed by "Draft candidates → verify → accept" and a batched token diagram with checks. +A small note below the inset: "Select one mode per run". +Use the exact phrase "Same event for fair ON/OFF benchmarks" as a small footer near that inset. + +CRITICAL FACTS AND ACCURACY: +- The LLM receives structured numerical / tracking evidence, not video pixels. Do not draw a direct camera-to-LLM arrow. +- Trigger concerns current group occupancy sustained for 1.5 seconds, never cumulative entries or a per-person dwell-time threshold. +- Freeze and persist event evidence BEFORE LLM processing. +- Tool plan precedes actual local alert and console notification; actual tool results are supplied for the report stage; report is actually saved. +- ON/OFF are alternative decoding settings of one local LLM, NOT two simultaneously running models. +- MTP affects both LLM tool planning and LLM report generation, never YOLO, tracking or database writes. +- This is a video demo, do NOT label the input "live camera". +- Do not include invented speed numbers, cloud services, external messaging, identity or danger detection. +- All prose is English, preserve the ≥ sign, spell Qwen3.5-4B and ByteTrack exactly. +- Text must be readable when the image is placed 1000 pixels wide in a wiki. Prefer sparse layout and accurate arrows to extra decoration. No captions like "Figure 1", no watermark. diff --git a/static/img/jetson-mtp-draft/english-image-prompts.json b/static/img/jetson-mtp-draft/english-image-prompts.json new file mode 100644 index 00000000000000..587e39d6cf66c3 --- /dev/null +++ b/static/img/jetson-mtp-draft/english-image-prompts.json @@ -0,0 +1,27 @@ +[ + { + "filename": "jetson-mtp-cover-en.png", + "original_filename": "Pasted image 20261023105746.png", + "prompt": "Edit target: the supplied cover image. Create its English-language edition for a technical wiki. Preserve the dark blue technology backdrop, NVIDIA Jetson logo, visual token-flow graphic, existing device photograph and composition. Replace ALL Chinese text. Exact headline: \"MTP on NVIDIA Jetson\". Exact smaller subtitle: \"Qwen3.5-4B · llama.cpp\". Exact explanatory line: \"Multi-Token Prediction for Edge AI\". Remove \"J501\" from the subtitle: the pictured enclosure is illustrative and the benchmark uses a Jetson AGX Orin 32GB, so do not identify the pictured enclosure as the benchmark device. No benchmark numbers or speed claims on this cover. All visible text must be English, legible and correctly spelled. Maintain wide 16:9 composition. Opaque background." + }, + { + "filename": "autoregressive-token-generation-en.png", + "original_filename": "Pasted image 20261021111409.png", + "prompt": "Edit target: supplied six-panel autoregressive decoding diagram. Preserve its six-panel left-to-right process, light blue/green palette, rounded cards, brain/LLM symbols, arrows and lower context timeline. Replace all Chinese text with concise readable English. Panel headings verbatim: \"1. Enter a prompt\", \"2. Predict the next token\", \"3. Update the context\", \"4. Predict again\", \"5. Repeat\", \"6. Complete the response\". Prompt: \"Where can NVIDIA Jetson be used?\" Panel explanations respectively: \"The user asks a question\", \"Generate Token 1 from the prompt\", \"Append Token 1 and generate Token 2\", \"Append Token 2 and generate Token 3\", \"Continue until generation ends\", \"Combine the generated tokens into a response\". Use token pills \"Token 1\", \"Token 2\", \"Token 3\", not whole English words pretending to be actual tokenization. Final sample response: \"Robotics, industrial vision, and edge monitoring.\" Lower label \"Context at each step (schematic)\" and use \"Prompt\", \"Token 1\", \"Token 2\" etc. No Chinese text. Allow extra vertical room for legibility, but preserve overall wide strip layout and all arrows. Opaque white background." + }, + { + "filename": "prefill-vs-decode-en.png", + "original_filename": "Pasted image 20261021113558.png", + "prompt": "Edit target: supplied two-panel LLM inference diagram. Preserve the blue left / green right panels, prompt card, input token blocks, LLM cards, context cache and looping arrows. Translate ALL text into English. Left title \"1. Prefill\"; subtitle \"Process the input prompt and build context state\". Prompt card text \"Where can NVIDIA Jetson be used?\" Block label \"Input tokens\". Context/cache label \"Context state / KV cache\". Below bracket \"Process input tokens in parallel\". Right title \"2. Decode\"; subtitle \"Generate output tokens with sequential dependencies\". Each loop label \"Append the generated token to the context\". Token pills simply \"Token 1\", \"Token 2\", \"Token 3\", so English words are not misrepresented as tokenizer output. Bottom timeline left \"Prefill: process input\", right \"Decode: generate output step by step\". All text readable English only, no Chinese. Keep diagram conceptually correct, clean, wide landscape. Opaque white background." + }, + { + "filename": "autoregressive-vs-mtp-en.png", + "original_filename": "Pasted image 20261022110151.png", + "prompt": "Edit target: supplied side-by-side autoregressive vs MTP diagram. Preserve blue left panel and green right panel, four numbered serial passes on the left, proposal and verification flow on right. All Chinese text replaced by concise English. Left title \"Standard autoregressive decoding\"; repeated input pills \"Prompt\", \"T1\", \"T2\", \"T3\"; repeated model boxes \"Target model\"; generated pills \"T1\",\"T2\",\"T3\",\"T4\". Right title \"MTP-assisted speculative decoding\". Start \"Prompt\" -> \"Target model\" -> \"MTP proposer\". Proposer caption \"Draft candidate tokens\". Proposals \"T2\",\"T3\",\"T4\",\"X\". Next box \"Target verification\" and candidate pills T2/T3/T4 with green checks, X with red cross. Caption \"Accept the valid prefix; reject X\". Bottom context \"Prompt | T1 | T2 | T3 | T4\" -> \"Target model\" -> \"T5\". Both bottom result rows use identical illustrative \"T1 T2 T3 T4 T5 ...\" with label \"Verified output (schematic)\". Ensure arrows show drafts are verified before entering committed output. Add small note \"Illustrative candidates; not a measured draft-depth setting.\" No Chinese characters, extra numeric performance claims or watermark. Opaque background, landscape." + }, + { + "filename": "jetson-voice-assistant-pipeline-en.png", + "original_filename": "Pasted image 20261023094537.png", + "prompt": "Edit target: supplied five-stage dark horizontal speech pipeline. Preserve charcoal background, five rounded boxes, microphone/ASR/chip/TTS/speaker icons and connecting arrows. Remove every Chinese label and retain clear English-only stage labels, from left to right: \"User voice\", \"ASR\", \"Local LLM\", \"TTS\", \"Spoken response\". Secondary text under ASR \"Speech to text\"; under Local LLM \"On-device inference\"; under TTS \"Text to speech\". Under the pipeline put a small note \"MTP accelerates the LLM decode stage\". Do not imply MTP speeds up ASR or TTS. Correct any odd original icons only if needed for legibility, preserve general composition and colors. Wide horizontal image, opaque background." + } +] diff --git a/static/img/jetson-mtp-draft/image-audit.json b/static/img/jetson-mtp-draft/image-audit.json new file mode 100644 index 00000000000000..c1658d2562f37e --- /dev/null +++ b/static/img/jetson-mtp-draft/image-audit.json @@ -0,0 +1,84 @@ +{ + "date": "2026-10-23", + "gif_frames_inspected": [ + "middle", + "end" + ], + "images": [ + { + "name": "jetson-mtp-cover-en.png", + "size": [ + 1672, + 941 + ], + "frames": 1, + "alt": "NVIDIA Jetson illustration with Qwen3.5-4B, llama.cpp, and an MTP token-flow graphic.", + "matches_reviewed_local": true, + "url": "https://files.seeedstudio.com/wiki/Jetson/Application/jetson-mtp-cover-en.png" + }, + { + "name": "mtp_vs.gif", + "size": [ + 1920, + 1080 + ], + "frames": 210, + "alt": "MTP OFF on the left and MTP ON on the right generating Fibonacci code with Qwen3.5-4B on Jetson AGX Orin.", + "url": "https://files.seeedstudio.com/wiki/Jetson/Application/mtp_vs.gif" + }, + { + "name": "mtp_demo.gif", + "size": [ + 1600, + 596 + ], + "frames": 163, + "alt": "Video-based ROI tracking on the left, with MTP OFF and ON crowd-analysis results in the center and right panels.", + "url": "https://files.seeedstudio.com/wiki/Jetson/Application/mtp_demo.gif" + }, + { + "name": "autoregressive-token-generation-en.png", + "size": [ + 2169, + 725 + ], + "frames": 1, + "alt": "Autoregressive decoding adds each generated token to the context before predicting the next.", + "matches_reviewed_local": true, + "url": "https://files.seeedstudio.com/wiki/Jetson/Application/autoregressive-token-generation-en.png" + }, + { + "name": "prefill-vs-decode-en.png", + "size": [ + 2055, + 765 + ], + "frames": 1, + "alt": "Prefill processes the prompt on the left; decode generates output tokens step by step on the right.", + "matches_reviewed_local": true, + "url": "https://files.seeedstudio.com/wiki/Jetson/Application/prefill-vs-decode-en.png" + }, + { + "name": "autoregressive-vs-mtp-en.png", + "size": [ + 1774, + 887 + ], + "frames": 1, + "alt": "Standard decoding on the left; MTP candidate drafting and target-model verification on the right.", + "matches_reviewed_local": true, + "url": "https://files.seeedstudio.com/wiki/Jetson/Application/autoregressive-vs-mtp-en.png" + }, + { + "name": "jetson-voice-assistant-pipeline-en.png", + "size": [ + 2171, + 724 + ], + "frames": 1, + "alt": "Voice-assistant pipeline from speech recognition through a local LLM to speech synthesis.", + "matches_reviewed_local": true, + "url": "https://files.seeedstudio.com/wiki/Jetson/Application/jetson-voice-assistant-pipeline-en.png" + } + ] +} diff --git a/static/img/jetson-mtp-draft/jetson-mtp-cover-en.png b/static/img/jetson-mtp-draft/jetson-mtp-cover-en.png new file mode 100644 index 00000000000000..69489b634f3bcc Binary files /dev/null and b/static/img/jetson-mtp-draft/jetson-mtp-cover-en.png differ diff --git a/static/img/jetson-mtp-draft/jetson-voice-assistant-pipeline-en.png b/static/img/jetson-mtp-draft/jetson-voice-assistant-pipeline-en.png new file mode 100644 index 00000000000000..a3c2ffb3ada3d4 Binary files /dev/null and b/static/img/jetson-mtp-draft/jetson-voice-assistant-pipeline-en.png differ diff --git a/static/img/jetson-mtp-draft/prefill-vs-decode-en.png b/static/img/jetson-mtp-draft/prefill-vs-decode-en.png new file mode 100644 index 00000000000000..c87ed65d828895 Binary files /dev/null and b/static/img/jetson-mtp-draft/prefill-vs-decode-en.png differ diff --git a/static/img/jetson-mtp-draft/prose-revision.json b/static/img/jetson-mtp-draft/prose-revision.json new file mode 100644 index 00000000000000..224ace3b55832d --- /dev/null +++ b/static/img/jetson-mtp-draft/prose-revision.json @@ -0,0 +1,13 @@ +{ + "before_prose_words": 3381, + "after_prose_words": 2623, + "prose_reduction_percent": 22.4, + "code_blocks_preserved": 12, + "artwork_sha256": { + "jetson-mtp-cover-en.png": "ea70e475c254beea9c7767448a30771d9d4fda7dfd81cc100da82241a9428759", + "prefill-vs-decode-en.png": "68ba5f7172dace8bfe61de66736921890878b12a778a7bab213c4ae19fc67483", + "autoregressive-vs-mtp-en.png": "d312a08027c995ae56240316646879d4f05f52f88faefbb58354d2459421c5e1", + "autoregressive-token-generation-en.png": "53353df61aacbc369cd655425d654ee9afec1ec5d5f5921eaa9f4d15af6657e2", + "jetson-voice-assistant-pipeline-en.png": "9358cd7b0afd474464acda53556fac2b30864264ace3f5ca1cedd1be6b26ed22" + } +}